

In its early stages, many artificial intelligence applications primarily worked with one type of data. Language-processing tools accepted written words, image-recognition systems analyzed photographs, and speech-to-text software focused on audio. This approach created useful products, but it also divided interaction with AI into several separate steps. Users had to describe an image in words, transcribe a recording into text, or convert a document into a suitable format before asking the machine to analyze it.
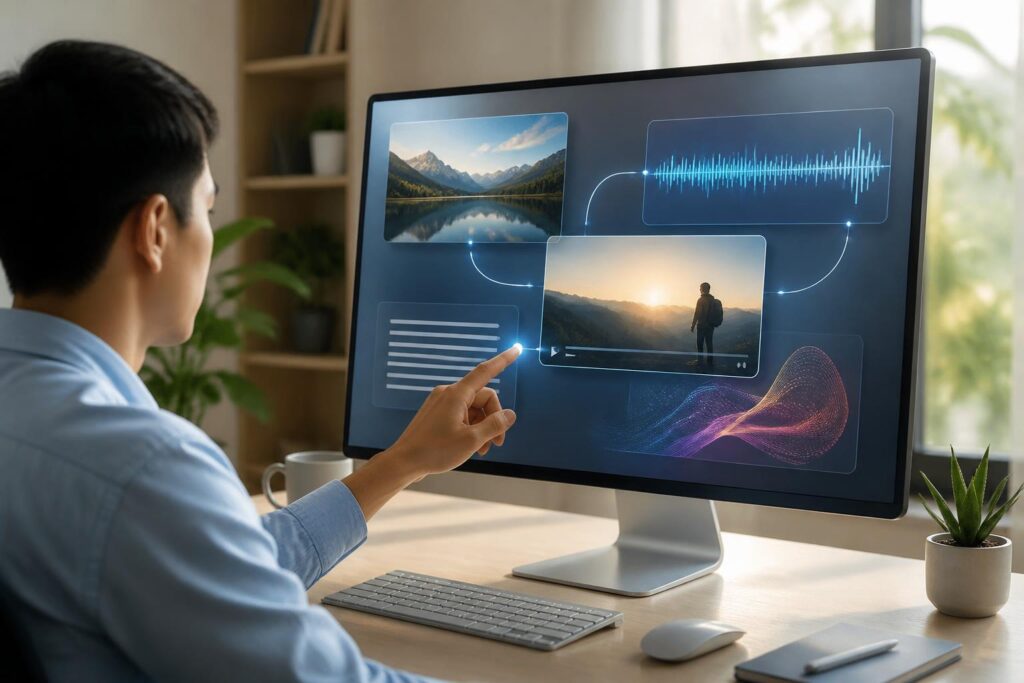
Multimodal AI, also known as multimodal artificial intelligence, aims to process multiple forms of information within the same workflow. A system may accept text together with an image, examine an audio clip alongside notes, or analyze a video using both its frames and speech. The goal is not merely to enable machines to “see” or “hear,” but to help them connect different signals and produce responses or actions that are better suited to the context.
How Does Multimodal AI Work?
Each type of data has its own structure. Text consists of words, sentences, and semantic relationships; images contain colors, shapes, positions, and objects; audio carries information about speech, sounds, rhythm, and silence. To process them within the same system, a model must convert these types of data into representations that a machine can compare and combine.
This process generally involves three basic ideas. First, the system receives data from one or more sources. The image may be a photograph, the audio may be a recording, and the text may be the user’s question. Next, the model identifies important features in each type of data. Finally, these features are placed within the same context so that the model can reason about the relationships between them.
For example, when a user provides an image of electrical equipment and asks, “Which component shows signs of an abnormality?”, the AI needs to do more than recognize shapes in the image. The system must also connect the image content with the question, determine which part the user is interested in, and express the result in language that is easy to understand. If the user also provides an instruction manual or additional information, the model can compare multiple sources of signals in a single processing step.
It is important to distinguish the ability to process multiple modalities from AI actually understanding the world like a human. A model identifies relevant patterns among data and generates responses based on its training process and input information. It does not have subjective experiences like a human, nor does it automatically know context beyond what is provided or what the system is permitted to access.
Common Forms of Interaction
Text Combined with Images
This is the most visible form in today’s AI tools. Users can upload photos of documents, diagrams, tables, products, or display errors and then ask questions in writing. AI can help summarize visible content, describe a layout, explain a chart at a general level, or suggest the next steps for checking something.
In education, students can use a photo of an exercise to ask for an explanation of how to solve it rather than simply receive the answer. At work, employees can ask the system to organize information from a table or convert the content of an image into an editable draft. However, the result still depends on image quality, text clarity, and the ability to recognize context. A document that is obscured, photographed at an angle, or filled with specialized symbols can easily lead the AI to misinterpret it.
Audio Combined with Text
With audio data, AI can convert speech into text, identify what the user is asking, and generate a response in writing or speech. This form of interaction is suitable for situations in which users are on the move, need to record ideas quickly, or want to communicate with software more naturally.
Audio processing is not limited to transcribing speech. The system can also use the context of what was said to summarize content, identify the main topic, or reorganize scattered ideas. Nevertheless, noise, regional accents, multiple people speaking at once, and specialized terms can all reduce accuracy. Users should treat a transcript or summary as a draft that needs to be checked, especially when the content relates to important decisions.
Video Combined with Multiple Data Sources
Video is a more complex type of data because it contains a sequence of images that changes over time, audio, and sometimes text displayed on the screen. A multimodal system can analyze short video clips to describe what happens, find a relevant moment, or summarize the content. When combined with a specific question, AI can focus on one aspect instead of merely describing the entire video.
However, analyzing video does not mean having perfect observational ability. An action that happens very quickly, an obstructed camera angle, unclear audio, or an event outside the frame can all make the conclusion inaccurate. Therefore, users should not treat an automated response as a complete record of everything that happened.
Practical Applications and Notable Benefits
A major strength of multimodal AI is that it reduces the number of conversion steps between people and software. Instead of retyping all the content from a sheet of paper, users can send an image directly to the system. Instead of describing a screen error in several sentences, they can send a screenshot along with a specific request. This makes using AI tools more similar to the way people exchange information in everyday life.
In customer service, product images or photos of a problem can supplement a written description. In the office, photos of minutes, planning tables, and meeting notes can be organized into a draft for employees to edit. In content creation, users can start with a written idea, a sketch, or a recording and develop it into multiple formats.
This technology also has the potential to support accessibility. People who have difficulty reading small text can use a tool to read the content in an image. People who cannot easily operate a keyboard can communicate by voice. These benefits are meaningful only when the system provides clear descriptions, allows users to control their data, and does not turn automated assistance into a new barrier.
Limitations and Risks to Consider
The ability to accept multiple types of data does not guarantee that the answer will always be correct. AI may misidentify an object, misread handwriting, overlook a detail in an image, or draw conclusions that go too far based on incomplete signals. An image that seems familiar but lacks information about time, location, and purpose can lead to multiple interpretations.
Privacy risks also deserve attention. Photos may contain faces, addresses, account numbers, or internal documents. Audio recordings may contain the voices and information of people who have not agreed to share them. Before uploading data to an AI service, users should review the service’s policy, remove unnecessary information, and consider whether the data is appropriate to put into the system.
Multimodal AI can also produce biased observations if the training data or input data lacks representation. A description of a person, place, or behavior should not be regarded as an objective assessment simply because it was generated using technology. In fields such as healthcare, law, recruitment, finance, or safety, AI feedback needs to be reviewed by a responsible person and should not be the sole basis for a decision.
How to Use It More Effectively
To obtain useful results, users should clearly state what type of data they have provided and what task they want the AI to perform. A request such as “analyze this image” is usually too broad. Instead, users can specify what information needs to be extracted, which parts should be ignored, what format the output should take, and how uncertain points should be marked.
The quality of the input data is just as important as the question. Images should be sufficiently bright and should not crop out relevant sections; audio files should have limited background noise; and videos should have a duration appropriate to the task. If important information is spread across multiple sources, users can provide each part and ask the AI to identify the relationships between them rather than make guesses while data is still missing.
After receiving an answer, check details that could have consequences if they are wrong. Compare numbers, proper names, times, conditions, and conclusions with the original documents. When AI is uncertain, users should ask the system to state its limitations clearly instead of forcing it to give a definitive answer. This approach helps AI become a tool for supporting thought and information processing, rather than a complete replacement for human judgment.
The Outlook for Multimodal AI
Multimodal AI is blurring the boundaries between tools that read, listen, see, and converse. In the future, many software applications may be able to receive information from different channels and coordinate it within a more seamless workflow. Users will not necessarily need to know in advance what format their data belongs to; they will only need to explain the problem and provide what they have.
Nevertheless, technical progress needs to go hand in hand with principles of transparency, data protection, and accountability. The more capable a system is of processing multiple sources of information, the more it needs to tell users which data it used, which parts were directly observed, and which parts were inferred. Multimodal AI can make access to technology more natural, but its value still depends on data quality, how questions are asked, and human review.
