


Many generative AI systems can write emails, summarize documents, or answer questions in natural language. However, the ability to express ideas fluently does not mean that a system always has the latest information or accurately understands an organization’s private data. When users ask about an internal regulation, a specific set of records, or content that was recently updated, a model cannot rely solely on what it learned during training.
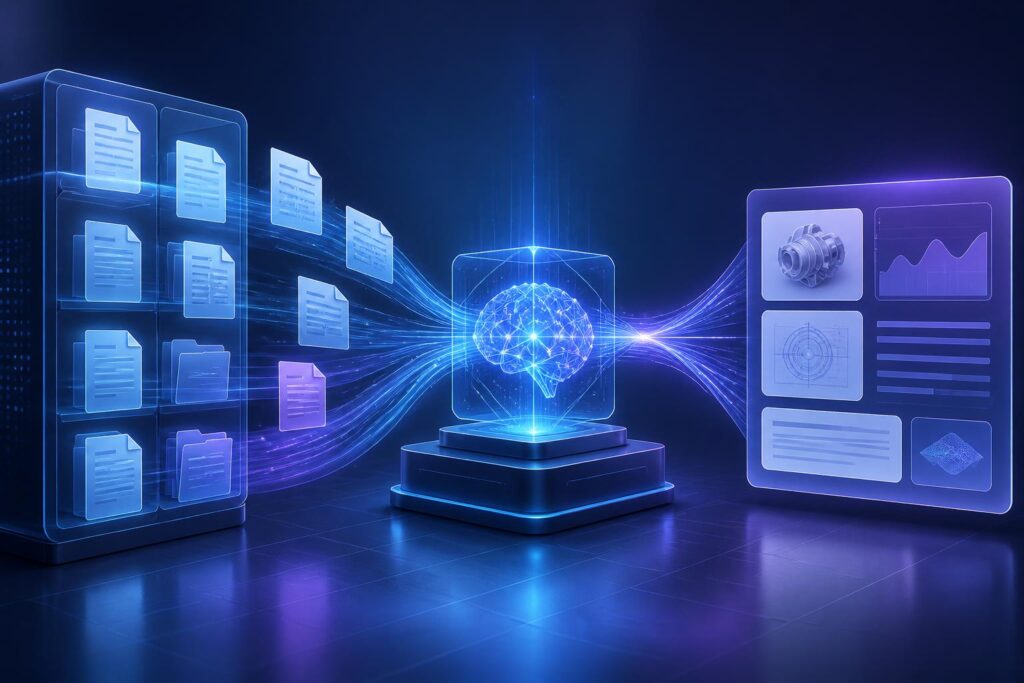
RAG, short for Retrieval-Augmented Generation, is commonly translated as generation augmented by retrieval. It is an approach that combines two activities: first, searching for relevant content in a data repository, and then providing the retrieved content to an AI model so it can generate an answer. Instead of requiring the model to remember everything on its own, RAG allows the system to refer to appropriate information sources when processing a request.
This approach does not turn AI into an absolutely accurate tool. RAG is simply an architecture that improves the information foundation of an answer. If data is missing, outdated, irrelevant, or retrieved incorrectly, the final result may still be unreliable. Therefore, understanding RAG should begin with both its benefits and its limitations.
How Does RAG Work?
A RAG process usually begins when a user submits a question. The system analyzes the request, converts it into a suitable form for searching, and then queries a data repository prepared in advance. This repository may contain instructional documents, workflows, frequently asked questions, product records, or other materials that the organization permits the system to use.
The search results are not necessarily entire documents. The system typically selects the content segments considered most relevant to the question. These segments are added to the request’s context before it is sent to the language model. The model then generates an answer based on the original question and the information just retrieved.
In many implementations, documents are divided into smaller segments before being indexed. Splitting documents helps the system find the part closest to the question instead of having to provide the entire document repository every time it processes a request. Content may be represented as data for keyword-based searching, semantic searching, or a combination of both approaches. The choice of technique depends on the type of document, language, data structure, and requirements of the application.
RAG can be thought of as an employee looking something up before answering a customer. Rather than relying only on general memory, the employee opens the right manual, finds the relevant regulation, reads the necessary section, and then explains it to the person asking. If the manual does not contain the required information or the employee opens the wrong document, the answer will still have problems. The difference is that in an AI system, the search and content-generation steps are carried out by software according to a predefined process.
Why Is RAG Useful in Practice?
The first benefit of RAG is that it helps AI access private data without necessarily retraining the entire model. A business may want to build an assistant that answers questions based on internal documents, even though those documents were not included in the model’s original training data. With RAG, the organization can connect the model to a controlled data repository that can be updated as needed.
The second benefit is the ability to reflect changes in information. Workflows, price lists, policies, or instructions may be revised over time. If the system is designed to update the data repository, it has the opportunity to use a newer version when answering. This differs from treating the model’s knowledge as a fixed memory that cannot be changed quickly.
RAG can also help users verify the basis of an answer. A well-designed system may display the name of the document, an excerpt, or the location of the source that was used. This information does not automatically prove that the answer is correct, but it allows readers to cross-check it rather than blindly accepting the content.
In environments with many documents, RAG can also reduce the time spent searching manually. Users can ask questions in natural language instead of remembering the exact file name or keywords in a document. However, this capability is valuable only when the data repository is organized properly and the system has corresponding access-control mechanisms.
How Is RAG Different from Retraining a Model?
Retraining or fine-tuning a model is generally intended to change how the model performs a task, responds in a particular style, or processes a certain type of data. This process may require carefully prepared data, computing resources, and post-training evaluation. The specific content that the model can answer about still depends on the data and the way the system is deployed.
RAG focuses on providing external context when the user asks a question. When documents change, the system can update the retrieval repository instead of repeating the entire training process. Therefore, RAG is often suitable for situations in which information changes frequently or needs to be managed as a separate source.
These two approaches are not mutually exclusive. A system can use a model fine-tuned for a particular response style while also using RAG to retrieve content from a document repository. Regardless of which option is chosen, the organization still needs to clearly define its objective: whether it wants to improve how the model responds, add contextual knowledge, or combine both.
Commonly Overlooked Issues When Building a RAG System
Data quality is fundamental. A document repository containing many duplicate versions, text with important sections cut off, unclear titles, or outdated content will reduce retrieval quality. AI may generate an answer that sounds reasonable based on data segments that are no longer appropriate. Therefore, updating, classifying, and removing outdated documents are tasks just as important as choosing the model.
How documents are divided also affects the results. If segments are too short, the system may lose accompanying definitions, conditions, or exceptions. If segments are too long, the necessary information may be mixed with a great deal of irrelevant content. There is no single fixed size that is suitable for every type of document. Legal texts, technical instructions, frequently asked questions, and tables may require different processing methods.
The ability to find the right documents is not enough to guarantee a good answer. The system must also select the right number of content segments and arrange them according to their relevance. If too little information is included, the answer may omit important conditions. If too much is included, the model may become distracted or confuse different regulations.
Access rights are another issue that cannot be taken lightly. An internal assistant should not provide sensitive documents to someone who is not authorized to view them simply because those documents are relevant to the question. Access control needs to be implemented at the retrieval stage, rather than relying only on a prompt instructing the model to conceal information on its own. When designing RAG, it is necessary to consider which data may be searched, who may view which data, and how the answer should leave an audit trail.
Does RAG Eliminate Incorrect Answers from AI?
No. RAG can reduce some errors caused by the model’s lack of information or reliance on outdated knowledge, but it is not an absolute guarantee. The system may still retrieve the wrong text, misunderstand the request, combine incompatible pieces of content, or overstate what the source allows it to conclude.
Another risk is that the source documents themselves may contain contradictions. When two texts provide different instructions, the system needs to know which document is in effect, which one takes priority, and in which cases the matter should be referred to a human. Without clear rules, the model may select a segment that appears suitable without recognizing the conflict between sources.
Therefore, RAG answers should be evaluated using sets of real-world questions. Builders need to check not only whether the answers are correct, but also whether the system finds appropriate sources, omits important conditions, or knows how to say that the available data is insufficient. In high-consequence fields, AI should support information retrieval and drafting, while the final decision should still be made through an appropriate oversight process.
How to Use RAG Responsibly
For users, it is important to ask clear questions and read the sources if the system provides them. When an answer concerns internal documents, users should check the update date, scope of application, and exceptions. The fact that an answer includes citations should not be treated as sufficient evidence to skip the verification step.
For organizations, the process should begin by identifying which data repositories truly need to be included in the system. Documents should have an owner, a validity status, and an update process. Content that is not permitted for retrieval purposes should be excluded or protected through access-control mechanisms. In addition, organizations should record cases in which the system provides incomplete or incorrect answers or cannot find information, so that the process can gradually be improved.
Users should also be clearly informed that they are interacting with a document-based support system, not an automated decision-making authority. The interface can encourage users to view sources, request clarification, and forward complex issues to the responsible personnel. Transparency about limitations is often more useful than creating the impression that AI always knows the answer.
Conclusion
RAG is a way of building AI systems in which the model not only generates content from existing knowledge but also retrieves relevant information before responding. As a result, AI can work more closely with an organization’s private documents, updated content, and specific context.
However, RAG is not an automatic bridge that turns disorganized data into reliable knowledge. Its effectiveness depends on source quality, indexing methods, access-control mechanisms, the ability to detect conflicts, and the evaluation process. When deployed with realistic expectations, RAG can become a useful layer of support between human information repositories and AI’s ability to express ideas. When treated as an absolute guarantee, it may only make old errors more convincing.
