

During the early stages of the generative AI wave, most users interacted with systems by entering questions in text form and receiving written answers. This approach still plays an important role, but people’s practical needs often involve more than one type of data. A doctor may need to examine an image alongside a medical history, a technician may have to read instructions while observing images of equipment, and a teacher may want to combine written material, diagrams, and recordings in the same process. This is the context driving the development of multimodal AI.
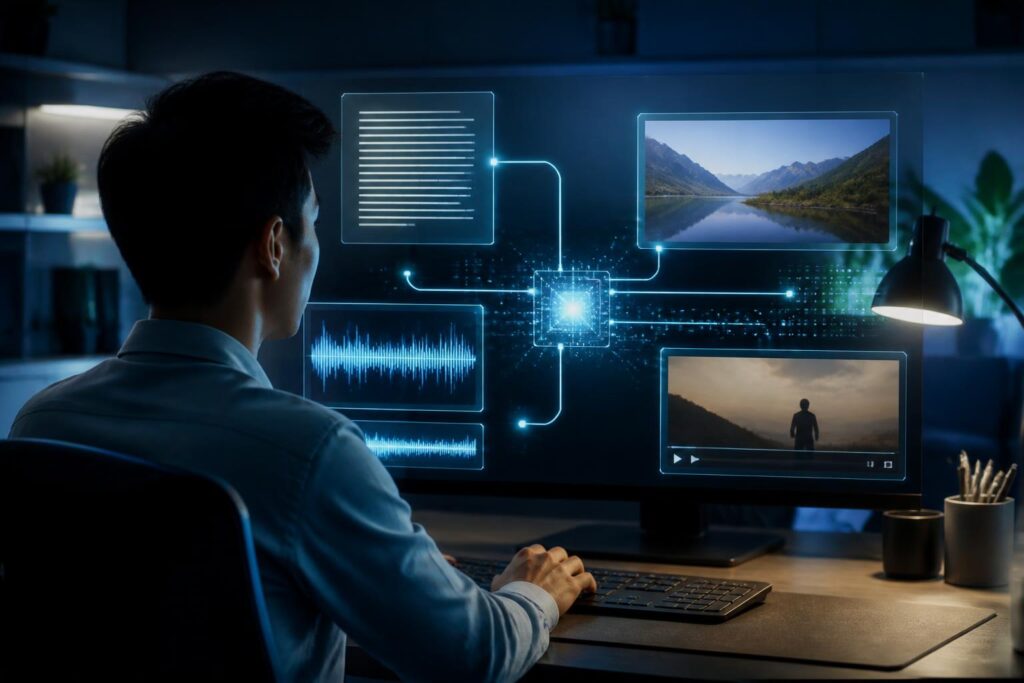
Multimodal AI is a group of systems capable of receiving, analyzing, or generating different types of data. These types may include text, images, audio, video, and sometimes other specialized signals. What is notable is not merely that the system can process multiple formats, but also that it can connect information across them to form a more unified understanding of the user’s request.
How Is Multimodal AI Different from AI That Only Processes Text?
A system that only processes text typically receives input in the form of sentences, paragraphs, or documents and then generates a response in language. If users want to ask about a picture, they must describe it in words or use another tool to convert the image’s content into text. This approach can be useful, but it always risks missing details that are difficult to describe, such as position, color, charts, handwriting, or the relationships between elements in an image.
Multimodal AI is designed to work directly with multiple types of input. Users can provide an image and ask a question in text, upload a document containing a chart and request a summary, or submit a recording to receive a transcript and key points. In systems capable of generating multimodal content, the output can also go beyond text, such as images, speech, or content organized in multiple formats.
However, multimodal AI should not be understood as seeing, hearing, and understanding the world in the same way humans do. The system still operates through computational models trained to recognize patterns, relate input signals, and predict suitable results. A broader processing capability does not mean complete awareness, consistently correct reasoning, or the ability to replace expertise in every situation.
How Does This Technology Combine Different Types of Data?
At a general level, each type of data is converted into a form of representation that the model can process. Text is analyzed through linguistic units, images are examined through features related to shape and layout, while audio can be analyzed according to time and frequency signals. The system then attempts to place these representations into a shared relational space to determine the connections between them.
For example, when a user provides an image of a machine along with a question in text, the model does not merely identify individual regions of the image. It must also connect the question with the relevant details in the image. If the question refers to the control button on the left, the system needs to identify the corresponding location rather than simply list all the objects that appear. For a chart, the task also involves recognizing the title, axes, labels, and the trend being shown.
In the case of audio and video, the task is more complex because the data has a temporal dimension. A video consists not only of multiple frames, but also dialogue, background sounds, gestures, and changes in the surroundings. To answer correctly, a system may need to determine when an event occurred, what was said, and how the images relate to the dialogue. This is why multimodal tasks often require more processing capacity than a simple text request.
Applications Familiar to Users
In office work, multimodal AI can help read documents containing both text and tables, convert meeting content into text, and then organize the key points by topic. Users can also provide a photo of a document page and ask for an explanation of difficult-to-read sections, although the result still needs to be checked against the original. When working with multiple sources of information, the ability to combine data can reduce the need for manual conversion between tools.
In education, this technology can help explain diagrams, analyze each step in a problem written on paper, or create questions based on the content of learning materials. A science lesson can combine text, illustrations, and a simulation clip. Even so, teachers remain essential for determining learning objectives, checking accuracy, and adjusting explanations to suit learners’ levels.
In creative fields, users can begin with a written description, provide reference images, and request suggestions for multiple directions. Designers can use AI to sketch ideas, content creators can analyze product images, and communications teams can transform long-form content into multiple formats. The technology is most suitable when it serves as an assistant during the exploration and preparation stages, rather than automatically deciding on the entire final product.
In customer service, a multimodal system can receive questions in text, photos of product defects, or recordings describing a problem. This gives staff more information with which to classify requests and guide the next steps. However, issues involving safety, warranties, or customer rights should still be referred to authorized personnel rather than being handed over entirely to the model.
Limitations to Recognize Before Use
The ability to read multiple types of data does not guarantee that the system will always identify them accurately. Blurry images, skewed camera angles, poor lighting, difficult-to-read handwriting, or audio with considerable background noise can all reduce analytical quality. A chart without labels can also make it easier for the model to misunderstand the meaning of the data. The less clear the input users provide, the greater the likelihood of receiving an inaccurate answer.
Multimodal AI may also correctly combine individual details while reaching an incorrect conclusion about the relationship between them. For example, the system may identify an object in an image but mistake its function, or correctly read the numbers in a table but misinterpret the trend. When the answer is written fluently, users may be even more likely to overlook such errors. Therefore, clarity of expression should not be treated as evidence of accuracy.
Privacy is another issue that needs to be considered. Images may contain faces, addresses, personal documents, or internal information. Audio recordings and videos may also reveal the identities, voices, locations, and living contexts of multiple people. Before uploading data to an AI service, users should consider whether they have the right to use that data, which information needs to be obscured, and what storage policies the service applies.
Not every task requires multimodal AI. If the request is simply to find a word in a basic document, a conventional search tool may be faster and more suitable. Using a complex system for a small task can increase costs, processing time, and the risk of introducing sensitive data into an unnecessary workflow. The choice of tool should begin with the practical objective rather than with the appeal of the technology.
How to Use It Effectively and Responsibly
First, users should clearly state what they want the system to do, which data should be prioritized, and what form the result should take. A request such as “analyze this image” is often too broad. Instead, users can ask the system to describe the main elements, identify parts that remain difficult to determine, and separate what is directly observed from what is inferred. Specific instructions make it easier for users to check the results.
Input quality also needs attention. When possible, users should provide sufficiently well-lit images, documents with suitable resolution, and audio clips with little background noise. If a document is long, dividing it into relevant sections can make the checking process more convenient. Users should not simply upload data and accept the first answer, but should ask follow-up questions when they notice unclear or contradictory points.
For important information, results should be compared with the original documents or reviewed by a qualified professional. This is particularly necessary in fields such as healthcare, law, finance, engineering, and workplace safety. AI can help read, organize, and suggest, but responsibility for decision-making still belongs to the people or organizations using the system. If the results could affect another person’s rights, health, or safety, human review should not be eliminated simply because the tool responds quickly.
Organizations also need to establish internal rules regarding which data may be entered into the system, who has the right to use it, how outputs are stored, and how errors are handled when they are discovered. Employees should be guided to understand that multimodal AI is a support tool, not a default source of truth. Recording cases in which the system misidentifies something can help organizations improve their processes and identify situations that should not be automated.
The Outlook for Multimodal AI
In the future, the boundaries between tools for processing text, images, audio, and video may continue to blur. Users will expect to interact with systems more naturally, moving from speaking to sending images, from watching videos to asking questions, and receiving responses in suitable formats. A workflow might begin with a conversation, continue with visual documents, and end with a summary or action plan.
However, the value of multimodal AI does not lie in putting as much data as possible into a single system. Its real value depends on data quality, the suitability of the tool, the ability to verify results, and how people take responsibility for the outcomes. The more types of information the technology can process, the more important transparency, security, and oversight become.
Multimodal AI opens up a way of interacting that more closely resembles everyday work, where information does not exist separately as text, images, or audio but often appears in combination. Understanding the technology’s capabilities and limitations will help users take advantage of it as a flexible assistant while avoiding the assignment of more decision-making authority than necessary. When placed within a process with clear objectives and human oversight, multimodal AI can become a useful tool for understanding, connecting, and transforming information.
